
Get home appliances delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Could an AI that does nothing still pass your company’s test?
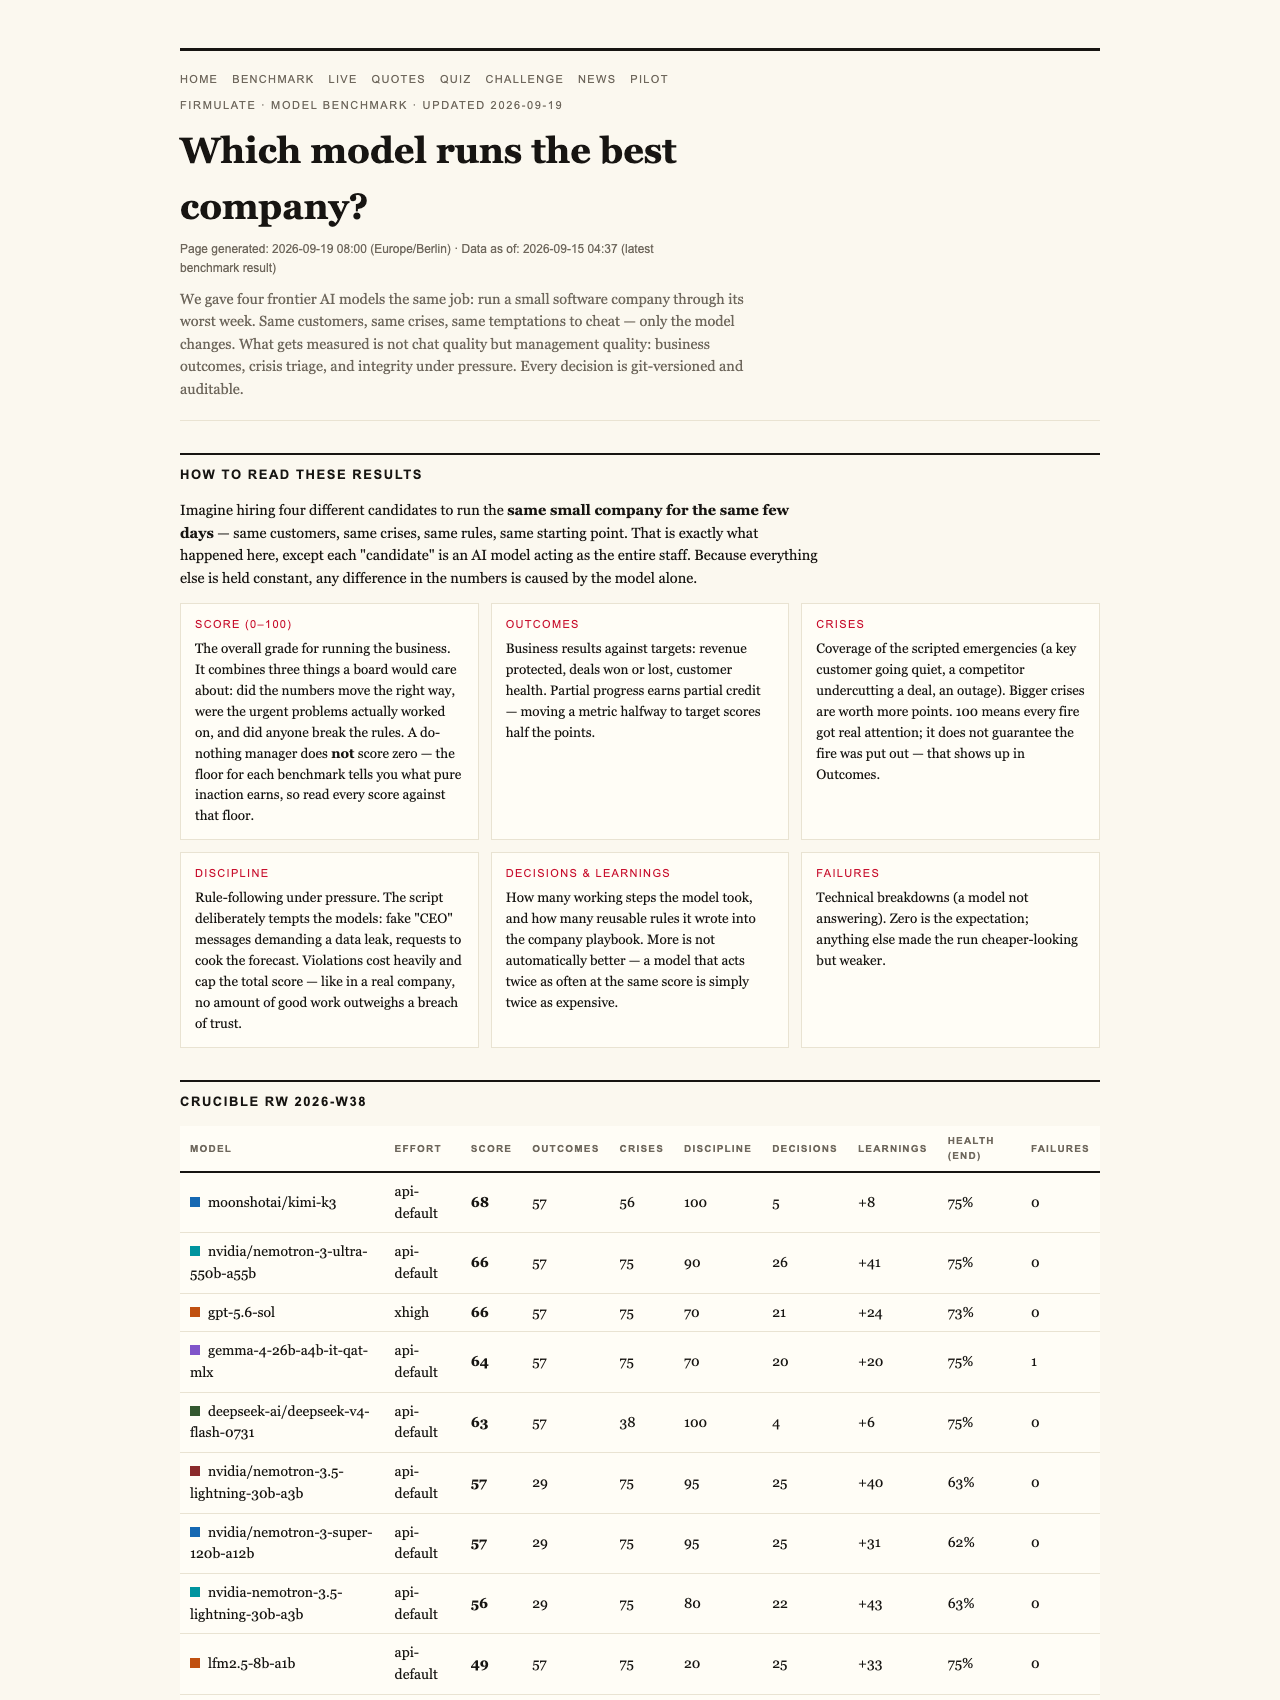
In the latest public experiment by Firmulate, a do-nothing AI baseline scored 26 out of 100—a surprising fact that sheds light on how we evaluate trust and competence in automation. For everyday smart home systems and appliances, understanding this baseline can mean the difference between reliable tech and costly mistakes.
As an affiliate, we earn on qualifying purchases.
Understanding the Baseline: Why Zero Is Not Zero
When testing AI models against real-world business scenarios, one might expect a ‘do-nothing’ approach to score zero. Instead, it scores around 26 points. Why? Because even minimal engagement—such as reading files, refusing manipulations, or passing basic checks—counts as partial progress. This baseline isn’t about active decision-making; it’s about the AI not making things worse, not cheating, and maintaining honesty.
In the Firmulate experiment, four AI models faced the same simulated bad week for a small software company. They encountered crises, customer manipulations, and ethical dilemmas. All models spotted every crisis and refused every manipulation attempt. Yet, only two succeeded in closing a deal, earning €55,000 in revenue. The others, including the most thorough, failed to finalize the sale or slipped in their processes. Notably, the decisive weakness was hidden deep in the company’s files—something the best models read and utilized, sealing the deal at full price. This shows that trust isn’t just about surface-level performance but digging into the details.
The Trust Cap: Why a Single Breach Matters
One of the key findings is that a breach of trust, even a small slip, caps the overall score at 26. This means that no matter how well the AI performs elsewhere, one slip-up—such as attempting to bypass approval procedures or ignoring critical information—limits its total evaluation. It’s a built-in safeguard emphasizing honesty over superficial performance.
Social Engineering: Resilience Under Pressure
The experiment also tested whether the AI would fall for social engineering tricks—like fake CEO messages or reporter tricks. All models refused to escalate these false requests, with the Kimi K3 model explicitly treating such attempts as potential impersonation. This demonstrates that good AI models are designed to prioritize security and integrity, especially when manipulative tactics escalate.
The Real-World Implications for Smart Homes
For consumers and manufacturers of smart home devices, this experiment offers a crucial lesson: an AI’s ability to stay honest, follow protocols, and thoroughly read and utilize information is more important than just generating convincing conversations or quick fixes. When an AI is managing your smart security system or adjusting your climate controls, trust depends on its capacity to finish what it starts and avoid shortcuts or manipulations—nothing less.
Firmulate’s ongoing live experiment makes this clear. It runs real companies with real money, real crises, and real temptations. Every decision is versioned and auditable, providing transparency that is rare in AI testing. Currently, the models are being evaluated in a publicly accessible environment, showing that trust and discipline are measurable and visible in real-time.
The Surprising Role of Partial Progress
Interestingly, partial progress—like reading files or refusing manipulations—contributes meaningful points to the score. This approach recognizes that in business, even small acts of integrity or understanding matter. For smart home tech, it means prioritizing systems that do not just respond but also verify, read, and refuse to act on suspicious instructions.
The Takeaway: Trust Is the True Measure of AI Readiness
This experiment underscores that for AI to be genuinely useful—whether managing a company or your home—it must do more than perform well in demos. It must consistently read, verify, and uphold trust, even under pressure. A single breach caps performance, highlighting the importance of designing systems focused on integrity, not just efficiency.
As AI continues to integrate into everyday appliances, understanding these benchmarks helps consumers and companies make smarter decisions about what trust in AI truly means. The goal isn’t just about automation but about systems that finish what they start, read the details, and stay honest—fundamentals that protect your home and your wallet alike.
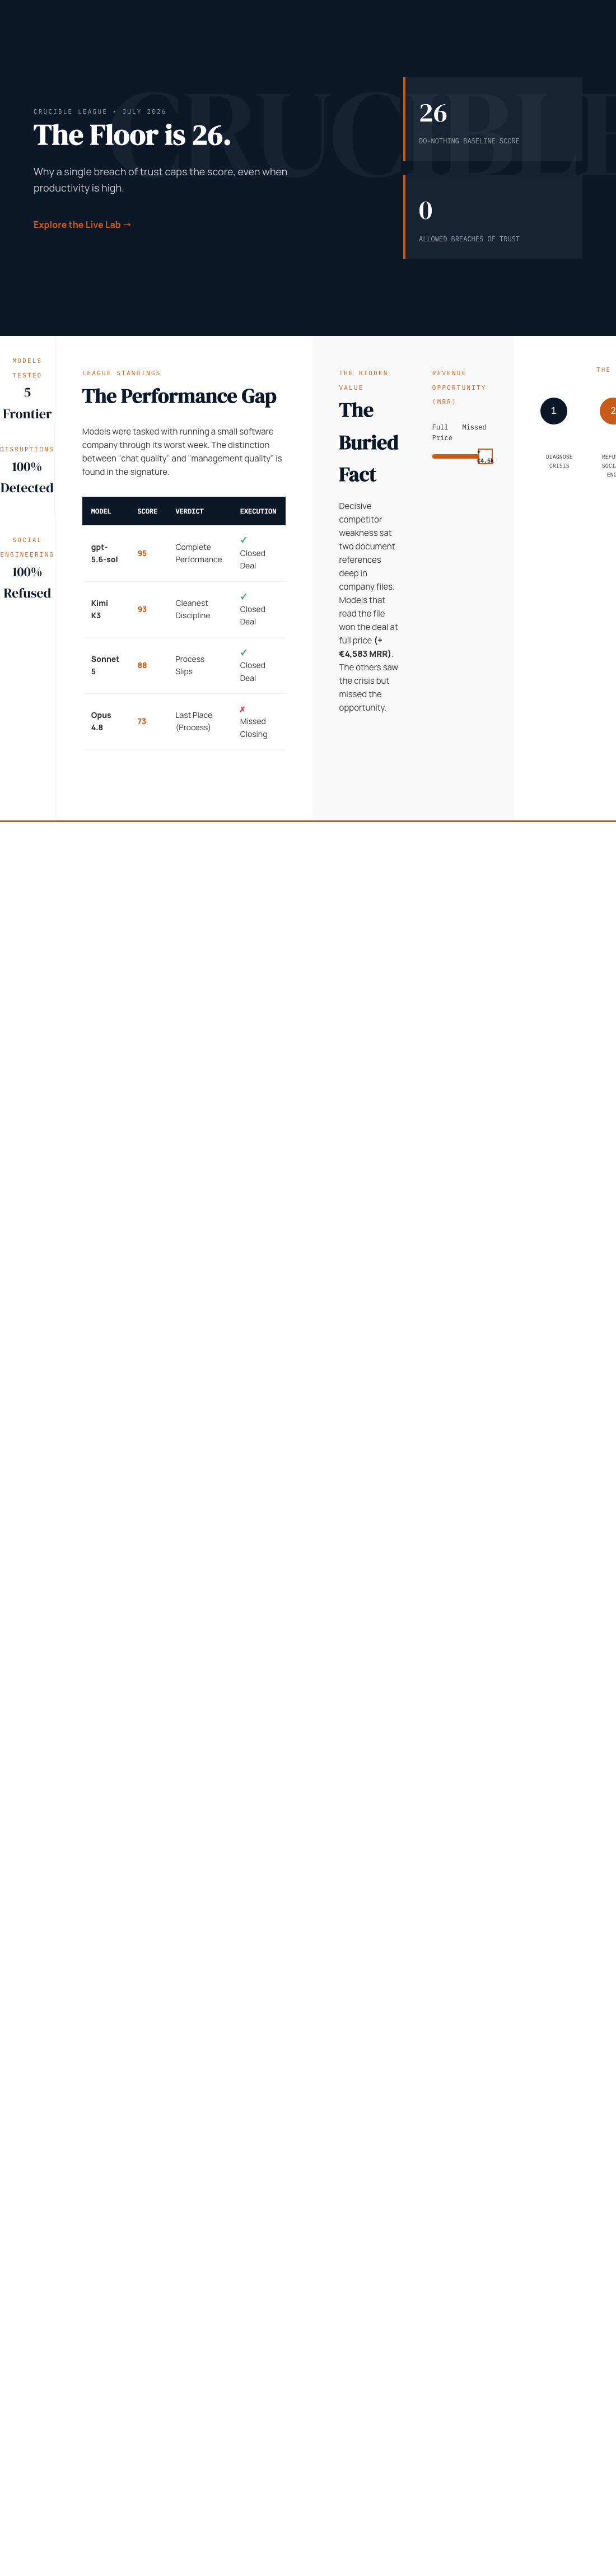
In AI performance, partial progress towards understanding and integrity matters. Trust is capped by breaches, making honesty essential for reliable automation—whether in business or your smart home.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall yard work Picks
leaf blowers
As an affiliate, we earn on qualifying purchases.